Technology News | November 12, 2026. AWS published a technical article on November 11 introducing the Universal Agent Evaluation Framework (UAEF), an approach for assessing AI agents built with different development frameworks.
The system is designed to help teams understand whether changes to prompts, tools or models improve agent behavior.
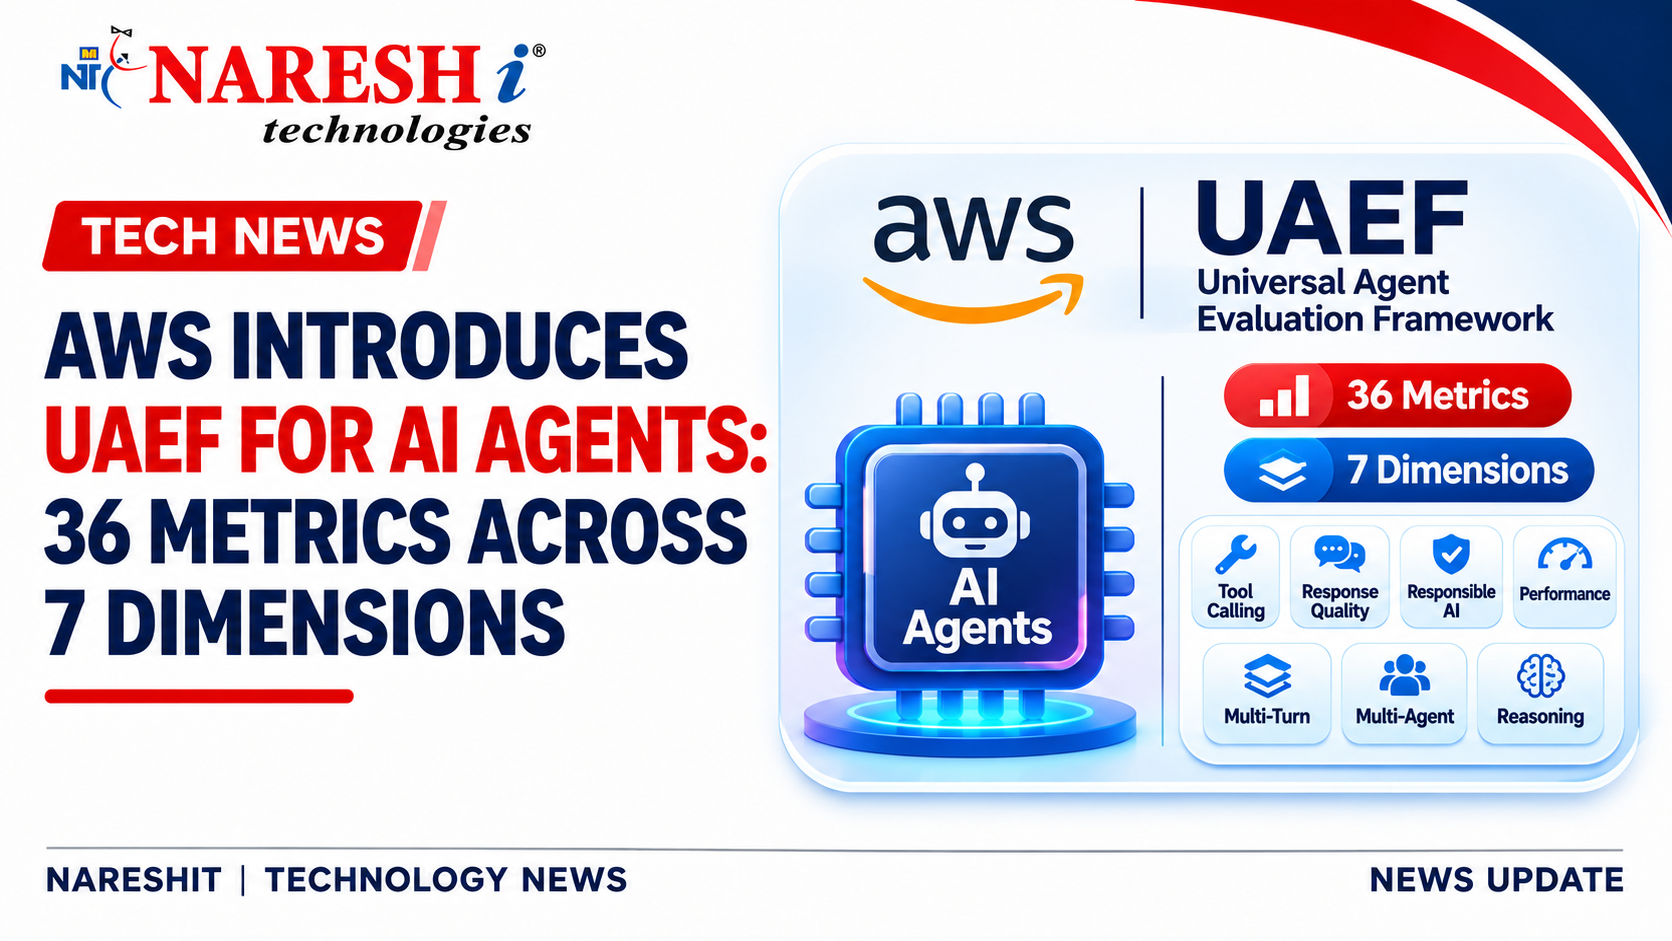
Quick Answer: UAEF standardizes AI agent execution traces and evaluates them with 36 built-in metrics across seven dimensions. AWS describes integrations for popular agent frameworks and experiment tracking to compare performance across versions.
What Is the AWS Universal Agent Evaluation Framework?
UAEF is a framework-agnostic evaluation system described by AWS for evaluating AI agents with a consistent scoring approach.
Agents developed using LangGraph, LangChain, Strands Agents and Amazon Bedrock AgentCore can produce different trace formats. UAEF converts supported execution records into a shared representation called AgentTrace.
This common format allows evaluation logic to work across supported frameworks instead of requiring separate scoring systems for each application.
What Are the Seven UAEF Evaluation Dimensions?
| Dimension | What It Checks |
|---|---|
| Tool Calling | Tool selection, ordering and arguments |
| Response Quality | Relevance, completeness, accuracy and grounding |
| Responsible AI | Safety, bias and prompt-injection resistance |
| Performance | Latency, token usage and throughput |
| Multi-turn | Context retention and conversation continuity |
| Multi-agent | Coordination and delegation between agents |
| Reasoning | Consistency and quality of logical reasoning |
AWS says each metric produces a normalized score between 0 and 1. Results can include deterministic checks or model-based judging, depending on the metric.
How Does UAEF Work?
The workflow begins with an agent and test inputs. An adapter captures or reads execution traces and converts them to the common schema.
The evaluation engine scores the chosen dimensions; experiment metadata can be stored in Amazon DynamoDB and full results in Amazon S3.
Teams can then compare current runs with baselines and investigate regressions.
AWS says the system was used by customers across 12 organizations in telecom, healthcare and financial services. This is information reported by AWS, not an independently measured industry adoption statistic.
Why Is This Development Important for Agentic AI?
AI agents may produce the correct final answer while making unnecessary tool calls, consuming excessive tokens or handling sensitive information poorly.
Traditional classification metrics alone cannot reveal every such failure. UAEF illustrates a broader evaluation approach that tests how an agent completes a task, not just what it returns.
Importantly, an evaluation score is not a substitute for runtime security controls. AWS explicitly distinguishes model-judged evaluation signals from operational safeguards.
What Should Python and Cloud Learners Understand?
Developers interested in AI agents can build foundations in Python, API integration, prompt design, tool calling, testing and evaluation datasets.
They can then study trace observability, cloud storage, experiment tracking and safe deployment practices.
For AI fundamentals, explore full stack data science with generative ai training in jntu.
For cloud infrastructure and deployment, explore devops with multi cloud training in jntu.
What Does This Mean for India’s Technology Professionals?
The AWS post describes a global technical framework and does not announce a specific India launch, hiring drive or job count.
For Indian developers, it is a useful example of the skills relevant to building and testing sophisticated AI applications: evaluation, software engineering, cloud architecture and responsible AI practices.
Frequently Asked Questions
1. What is UAEF?
UAEF is the Universal Agent Evaluation Framework described by AWS for consistent AI agent assessment across supported development frameworks.
2. When was UAEF introduced in the AWS technical post?
AWS published the article on November 11, 2026.
3. How many metrics does UAEF provide?
AWS reports 36 built-in metrics organized into seven evaluation dimensions.
4. Does UAEF work with LangGraph?
Yes. AWS describes adapters and examples for LangGraph and other supported frameworks.
5. Can UAEF replace AI safety controls?
No. Evaluation scores support assessment and comparison but do not replace security controls and runtime safeguards.
Conclusion
AWS’s UAEF work highlights a growing challenge in Agentic AI: measuring reliability consistently when applications use different frameworks, models and tools.
For developers, the practical lesson is to build evaluation into the development workflow rather than judging agents only by impressive demonstrations.
Official News Source
Publisher: AWS Artificial Intelligence Blog.
Original publication date: November 11, 2026.
Read AWS’s Original UAEF Technical Announcement
Editorial Note: This is an independently written educational summary of AWS’s published technical article. Product descriptions and adoption figures are attributed to AWS.